Git good
Go, go, GitOps
So, now I had a cluster spun up and ready to go. Naturally, the next step was to install services on it! There are two main ways of doing this: either "pushing" or "pulling" and there are tradeoffs to both.
The "push" method basically covers any way of installing applications into the cluster initiated from some external source. This includes locally running kubectl apply or helm apply, creating a Tofu module to install services, using Helmfile, etc. The major benefit of "pushing" services is that the cluster doesn't need to know or care how services are installed. Any of the previously mentioned methods would be treated identically by the cluster, and this would give me a lot of flexibility to choose how to install services in the future. It would also be the quickest way, as all I would need to do is add additional Tofu helm_release resources for each Helm Chart I wanted to deploy.
This would work great when running locally, but I really wanted to be able to update installed services without needing to always be at my laptop or on my home network. Typically, the installation would be run in a CI/CD pipeline (triggered, for example, when a new Git repository tag is created). However, this opens up a whole can of (security) worms. I would need to expose my cluster API to the internet, and then would need a way to say "only this CI/CD job can install services onto my cluster". This would require some kind of authentication mechanism, and ultimately (in the worst case) adds an attack vector where malicious actors might figure out how to get around the authentication and install arbitrary code into my cluster. Not good.
This is where the "pull" method shines. Instead of having some external authenticated system install things into the cluster, what if I had some service running in my cluster that "pulled" in services to install? This is generally how most popular GitOps tools work. The idea behind GitOps is that the Git repository should be the "source of truth" for what is installed. For example, let's say I decided to just install services locally using a Tofu module. I could write a module to install two services: Service A and Service B. I could even commit that file to Git for proper version control. However, the installation isn't directly connected to the file. I could, for example, forget to install Service B even though it is in the code. Or, I could install Service A and Service B, and then manually edit Service A in the cluster so the state is no longer accurately reflected by the installation file kept in Git, and then forget to update the file. This leads to the potential for "drift" between what is defined and what is installed.
GitOps aims to solve this by having some service running in a cluster. This service is responsible for installing and managing everything in the cluster. Going back to our example, the idea is to configure the GitOps service to tell it to install Service A and Service B. Then, the GitOps service reaches out, pulls the code for the services into the cluster, and installs them. It does this on some configured interval, and can even check to see if the installed services match their code, and if not will correct the drift. That's pretty nifty!
I think one of the big downsides of "pull" methods like GitOps is that it can add a lot of overhead and layers to just getting something installed. For example, let's say I'm still developing Service A and want to test it out in the cluster. If I want to install it with my GitOps service, now I need to set up a repository for the code, commit and push my changes, and point the GitOps service to my code so it can install Service A. Then I might need to wait for the configured interval to see changes (or manually adjust the GitOps reconciliation interval temporarily). This adds a lot of delay and steps when I just want to test something out. Ultimately though, I decided the security upsides were easily worth the slower development cycles. With a GitOps service, I wouldn't need to expose my cluster API at all outside of my home LAN, completely eliminating that attack vector!
The chicken and the egg
Keen readers might have noticed one teeny, tiny, super small issue. If I wanted to use GitOps to install services in my cluster, that would require having a GitOps service running in my cluster. So how would I install the GitOps service in the first place? A classic chicken-and-the-egg problem. To initially install a GitOps service, I wanted to integrate the installation into my existing Tofu cluster creation module. That way, I would be able to stick with my goal of spinning up the entire cluster with one command (excluding the creation of the VM). After that, I would want the GitOps service to manage itself. This is referred to as "bootstrapping".
With this in mind, I started by evaluating two of the most popular GitOps Kubernetes projects: FluxCD and ArgoCD. I have a decent amount of experience using Argo, and knew that while powerful, it could be a lot to set up and manage and has some annoying behaviors. While I had no experience with Flux, the more I read over the documentation the more I liked it. It was headless, offered a lot of flexible options for sources, and included a bunch of QoL features. Critically, I also found a recent blog article describing how to bootstrap Flux with Tofu. This was perfect! Surprisingly, I was unable to find any articles on how to bootstrap Argo using Tofu even though I expected this to be pretty common. That sealed the deal, I was going with Flux!
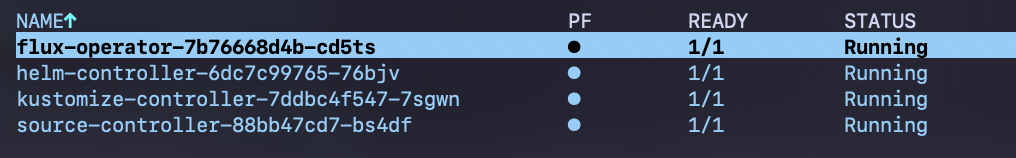
The blog article referenced the Flux Operator, which is a Kubernetes Operator for managing Flux deployments. It also includes a bunch of extra features, but for my setup I didn't want or need those. I mostly just wanted to use it to simplify my initial bootstrap of the Flux controllers. Following the article, I added the module to my Tofu file, created a FluxInstance and set up the operator ResourceSet. Running tofu apply again, everything worked! I saw the flux-operator-bootstrap Namespace and Job deploy, and then I saw the operator reconcile the FluxInstance and spin up the Flux controllers. Finally, I confirmed that the Flux deployment started reconciling itself so I could make updates to the deployment in the future without needing to apply the Tofu again!
Beginners Flux
So what app would I deploy with Flux first? Well, before I could start adding fun, new stuff, I had to take care of my chores. I actually already had a service running in the cluster: Cilium! Cilium was a tricky first candidate, because it too had a chicken-and-the-egg problem (noticing a theme?). The cluster needs networking in order to function, but I wanted to install and manage Cilium with Flux so it's easy to update in the future. I went through a lot of trial-and-error here, but I'll just summarize how I ended up handling this because it ended up being quite simple.
In the previous post, I used a helm_template Tofu resource to generate a set of manifests from the Cilium Helm Chart. Then I added those to the Talos machine patches so they were installed at cluster creation. My main concern was that the resources would already be considered "managed" by a Helm Release because it would be problematic to try and have a new Helm Release take ownership later. But it turns out that just using helm_template instead of helm_release doesn't mark any of the templated objects as owned by a Release. Helm can take ownership of existing resources. So as long as the Chart version and values were the same in my helm_template and Flux OCIRepository/HelmRelease, I could keep my existing initial bootstrap with the Talos machine patch, and then when Flux also installed Cilium, the Helm Release would simply end up taking ownership of the existing resources. I had one final concern about this method: what if running tofu apply again would break/overwrite the Flux-managed Release? But this also ended up being a non-issue! Talos only creates new resources, and never edits or destroys existing ones. Cool beans! I had a path forward and just needed to put it all together.
The first step was figuring out how to structure the files for services I wanted Flux to manage. While definitely not necessary for my personal homelab, I went ahead and set up Flux in multi-tenancy mode. With that model, I wanted each service to be a "tenant". After researching common patterns, I decided to create a setup where I could classify different tenants into some high level categories:
- Core services. These are services that are critical to the cluster functioning or enforcing security policies, need elevated privileges, and run in the
kube-systemnamespace. - Policies. This tenant doesn't include any running services, but instead contains cluster-wide policies to enforce workload configuration standards and protect the cluster from runtime threats.
- Infrastructure services. These are services that generally are required for most other applications but not critical for the cluster, such as operators, controllers, and components like
metrics-server. - App services. These are the actual things I want to run in the cluster, such as websites, game servers, etc.
I decided to split the tenant definition (OCIRepository/HelmChart and HelmRelease with values) from the list of tenants included in a cluster. This would allow me to easily enable or disable tenants. For Cilium, I created a gitops/tenants/cilium folder and added the OCIRepository (with Cosign keyless verification):
apiVersion: source.toolkit.fluxcd.io/v1
kind: OCIRepository
metadata:
	name: cilium
	namespace: kube-system
spec:
	# ...
	url: oci://quay.io/cilium/charts/cilium
	ref:
		tag: 1.20.0
	verify:
		provider: cosign
		matchOIDCIdentity:
		- issuer: ^https://token\.actions\.githubusercontent\.com$
			subject: ^https://github.com/cilium/cilium/.*$
And created the HelmRelease:
apiVersion: helm.toolkit.fluxcd.io/v2
kind: HelmRelease
metadata:
	name: cilium
	namespace: kube-system
spec:
	# ...
	releaseName: cilium
	chartRef:
		kind: OCIRepository
		name: cilium
	values:
		# The values I had originally been setting in Tofu that Talos provided.
		ipam:
			mode: kubernetes
		# ...
Then all I had to do was update the Tofu to pull the Chart version and values from these files:
locals {
	gitops_path = "${path.root}/../../gitops"
	cilium_tenant_path = "${local.gitops_path}/tenants/cilium"
	cilium_oci_repository = yamldecode(file("${local.cilium_tenant_path}/ocirepository.yaml"))
	cilium_helm_release = yamldecode(file("${local.cilium_tenant_path}/helmrelease.yaml"))
	cilium_chart_version = local.cilium_oci_repository.spec.ref.tag
	cilium_chart_values = local.cilium_helm_release.spec.values
}

data "helm_template" "cilium" {
	name = "cilium"
	namespace = "kube-system"
	repository = "oci://quay.io/cilium/charts"
	chart = "cilium"
	version = local.cilium_chart_version
	atomic = true
	# The `kube-system` namespace is created automatically.
	create_namespace = false
	dependency_update = true
	include_crds = true
	kube_version = var.machine_kubernetes_version
	wait = true
	values = [yamlencode(local.cilium_chart_values)]
}
Next, I created a file in my GitOps cluster directory (gitops/clusters/virgo/tenants) which would tell Flux to include Cilium in my cluster:
# gitops/clusters/virgo/tenants/core.yaml
apiVersion: fluxcd.controlplane.io/v1
kind: ResourceSet
metadata:
	name: core
	namespace: flux-system
spec:
	wait: true
	inputs:
	- tenant: cilium
	resources:
	- apiVersion: v1
		kind: ServiceAccount
		metadata:
			name: flux
			namespace: kube-system
		automountServiceAccountToken: false
	- apiVersion: rbac.authorization.k8s.io/v1
		kind: ClusterRoleBinding
		metadata:
			name: flux-kube-system
		roleRef:
			apiGroup: rbac.authorization.k8s.io
			kind: ClusterRole
			name: cluster-admin
		subjects:
		- kind: ServiceAccount
			name: flux
			namespace: kube-system
	- apiVersion: kustomize.toolkit.fluxcd.io/v1
		kind: Kustomization
		metadata:
			name: << inputs.tenant >>
			namespace: flux-system
		spec:
			interval: 1m
			retryInterval: 5m
			timeout: 5m
			serviceAccountName: flux-operator
			prune: true
			wait: true
			sourceRef:
				kind: GitRepository
				name: homelab
			path: gitops/tenants/<< inputs.tenant >>
			decryption:
				provider: sops
				secretRef:
					name: flux-decryption
Finally, I re-created the cluster and confirmed that Cilium was taken over by Flux after the initial bootstrapping! This ended up being a simple pattern I could apply to any workloads that needed to exist during cluster startup and managed by Flux afterwards. I ended up changing my Flux bootstrap to this approach, as I ran into a number of annoyances later with the provided module. The module is still a good option when creating clusters with Tofu, but it does add an extra Namespace, Job, RBAC, etc. that I could avoid thanks to the config patches Talos supports!
Secret ingredient
Speaking of chickens and eggs and such, it's time to talk about the secret ingredient: secrets! I knew I would need to figure out how to get secrets into the cluster for future services. One common way to handle this is to use some external secret store, like OpenBao and then External Secrets Operator to use the secrets in the cluster. However, even with these systems an initial secret is needed in the cluster to connect to the secret store. This is called the Secret Zero Problem, and it's very similar to the GitOps bootstrap issue. I wanted to avoid using a secret store service for now, as I won't need to manage a large number of secrets and plan to keep everything self-hosted. Luckily, there's an app for that: Flux (again)!
Flux supports automatically decrypting encrypted Kubernetes Secrets using SOPS. This means I can create a Secret object locally, encrypt it with a public key (so it's safe to store in Git), and then when the Secret is loaded into the cluster by Flux it will automatically be decrypted and have the correct secret value. The only requirement for this is that Flux needs a Secret with the corresponding private key to be in the cluster already. That private key secret is my Secret Zero. But before I could start thinking about how to solve the Secret Zero Problem, I had to decide what to encrypt my Secrets with.
Flux supports a number of encryption tools. One important factor I considered was how safe it would be to upload the encrypted data to my Git repository. Specifically, I was nervous about the potential exposure of this data after quantum computers might be powerful enough to break most common asymmetric encryption algorithms. You might be wondering "why is this important to worry about now if this hasn't happened yet?". Great question. The main concern is "harvest now, decrypt later" attacks, where attackers might harvest a bunch of encrypted data now, store it, and decrypt it at a future date when quantum computers are able to break the cryptography. Luckily, there are a lot of smart cryptographers out there who have developed post-quantum-safe encryption algorithms. Many companies are already updating to the safe encryption standards now, such as iMessage using PQ3, which is critical because it minimizes how much data can be harvested now and decrypted later.
Returning to my homelab setup, I found that Flux supports Age and recently updated to support Age post-quantum ciphers. Perfect! I got started by generating a key for Flux:
age-keygen -pq -o secrets/key-flux.txtThen I got the recipient (public key):
age-keygen -y secrets/key-flux.txtFinally, I created a .sops.yaml configuration file and added the Flux recipient:
stores:
	yaml:
		indent: 2
creation_rules:
- path_regex: gitops/.*\.yaml
	encrypted_regex: ^(data|stringData)$
	age: >-
		<key-flux-recipient>
To encrypt a Secret, all I need to do now is run:
sops -e -i path/to/secret.yamlNow I just needed to figure out how to get my Secret Zero (the key-flux private key) into the cluster during creation. Because I'm already provisioning the cluster locally using Tofu, I simply needed to add a Secret to the Talos machine config patches (I upgraded from Talos v1.13 to v1.14 after the last post, and Talos majorly changed how the machine configuration is structured which is why this might look different):
yamlencode({
	apiVersion = "v1alpha1"
	kind = "KubeInlineManifestConfig"
	name = "flux-decryption-secret"
	manifest = yamlencode({
		apiVersion = "v1"
		kind = "Secret"
		metadata = {
			name = "flux-decryption"
			namespace = "flux-system"
		}
		data = {
			"identity.agekey" = base64encode(file("${path.root}/../../secrets/key-flux.txt"))
		}
	})
})
Finally, I updated the Flux Kustomizations and configured them to use the new decryption secret in the spec:
decryption:
	provider: sops
	secretRef:
		name: flux-decryption
With all this set up, I can now safely encrypt any sensitive value I need to use in the cluster and store them in Git along with the rest of my manifests!
Hatching plans
So now we're finally ready to answer the age-old question: Which came first? The chicken or the egg? Clearly, the answer is a bootstrapped egg! While I'm excited to actually start deploying fun apps in the cluster, I've got one more piece I need to work on first: security! The next post will be all about the different layers of cluster security, as well as how to balance best-practices with the limited resource of a small homelab (and my personal time 😅). I hope you enjoyed this post, thanks so much for reading!